Using Event-Driven Architecture to Process Twitter Likes
 A single Twitter like is a small action. At scale, however, likes can become a continuous stream of events that applications may need to collect, process, store, and analyze. Imagine a social media analytics platform monitoring thousands of posts, while services such as Social Crow help support broader engagement strategies. When users like those posts, the system might update engagement counts, refresh dashboards, trigger analytics jobs, or send data to recommendation models. Handling every action through a tightly connected sequence of synchronous requests can become difficult as traffic grows.
Event-driven architecture offers another approach. Instead of requiring every system component to respond at the same moment, an action can be represented as an event and passed through infrastructure that allows different services to react independently.
What Is Event-Driven Architecture?
Event-driven architecture is a software design approach in which system activity is organized around events. An event represents something that has happened. In a social media context, examples could include a post being published, a user following an account, or a post receiving a like.
When a relevant event enters the system, one or more consumers can process it.
The component producing the event does not necessarily need to know what every consumer will do with the information. This separation is one of the main advantages of an event-driven design.
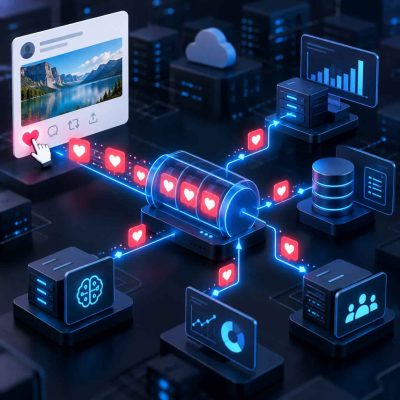
For example, an engagement service could receive information about a like and publish an event. A separate analytics service might update statistics, while another service stores information needed for reporting.
A Twitter Like Becomes an Event
In a basic implementation, the system first needs a legitimate way to receive or retrieve engagement information from the platform, subject to the current API access, permissions, rate limits, and policies.
Once the application identifies a relevant like, it can represent the activity in a structured format. An event might contain fields such as an event identifier, post identifier, event type, and timestamp.
The event is then sent to a broker, queue, or streaming platform. Rather than performing every downstream operation during the initial request, the producing service can finish its immediate work while consumers process the event separately.
This creates a useful boundary between receiving engagement activity and deciding what to do with it.
Message Brokers Help Decouple Services
A message broker or event-streaming platform often sits at the center of an event-driven system. Technologies such as Apache Kafka, RabbitMQ, or managed cloud messaging services can transport events between producers and consumers. They differ in how they handle delivery, ordering, retention, routing, and scaling, so the right choice depends on the application’s requirements.
Suppose a PostLiked event enters the system. Several services could respond independently. An analytics consumer might update engagement metrics. A data pipeline could send the event to long-term storage. Another service could use aggregated engagement signals as one input for identifying content trends.
Because these consumers are separated, adding a new use case does not necessarily require rewriting the service that originally received the engagement data.
Event-Driven Systems Can Handle Traffic Spikes
Social engagement is rarely distributed evenly. A post may receive a few likes over several hours and then suddenly attract thousands after being shared by a large account or connected to a breaking topic. Systems that expect steady traffic may struggle with these spikes.
Queues and event streams can buffer incoming activity and downstream processing.
If events arrive faster than a consumer can handle them, they can remain available for processing rather than requiring every downstream operation to complete immediately. Consumers can also be scaled horizontally when the architecture and workload support it.
This does not make scalability automatic. Engineers still need to consider broker capacity, consumer throughput, database performance, partitioning, and infrastructure limits. But an event-driven approach gives teams useful ways to separate ingestion speed from processing speed.
Duplicate Events Need Careful Handling
Distributed systems do not always deliver every event exactly once. A consumer may process a message successfully but fail before recording that completion. The same message might then be delivered again. Network failures, retries, or upstream behavior can also produce duplicate data.
If the application increments a like counter every time it receives an event, duplicates can create inaccurate results. One common response is to make consumers idempotent. An idempotent consumer can receive the same event more than once without applying the business effect repeatedly.
Unique event identifiers can help. A service might record which event IDs it has processed and reject duplicates. Other designs may use database constraints, upserts, or stateful stream-processing techniques. The appropriate solution depends on how strong the system’s consistency requirements are.
Ordering Can Matter
Not every event can be processed independently. Consider a system that receives both like and unlike events. If those events are processed in the wrong order, the stored state may no longer reflect the expected sequence of activity.
Event-streaming systems can preserve ordering within certain boundaries, such as a partition. Engineers may therefore choose a post ID or another suitable key when deciding how to partition events. However, stronger ordering requirements can limit scalability.
Before designing for strict ordering across an entire system, teams should determine where ordering genuinely matters. Many analytics workloads can tolerate eventual consistency, while other operations may require tighter controls.
Failures Should Be Expected
A consumer can fail because of malformed data, an unavailable database, a software bug, or a temporary network problem. Reliable event-driven systems are designed with these failures in mind.
Retry policies can allow temporary problems to resolve without losing the event. But uncontrolled retries can make an outage worse, so techniques such as exponential backoff may be appropriate.
Events that repeatedly fail processing can sometimes be moved to a dead-letter queue for investigation rather than blocking normal traffic.
Monitoring is equally important. Teams need visibility into consumer lag, processing errors, queue depth, throughput, and other indicators that show whether the pipeline is functioning properly.
Event Data Requires Responsible Handling
Social media data should not be collected simply because it is technically possible.
Applications need to work within the platform’s current developer terms and applicable privacy and data protection requirements. Teams should also consider whether they genuinely need user-level information.
For many analytics tasks, aggregated engagement counts may be sufficient. Collecting unnecessary personal information increases privacy, security, and compliance responsibilities.
Retention policies also deserve attention. Data should not remain in storage indefinitely without a legitimate reason.
Design Around the Business Need
Event-driven architecture can be a strong fit for processing Twitter likes when an application needs to handle large or irregular volumes of engagement activity across several independent services.
But it adds complexity. Brokers must be operated or managed, consumers need monitoring, duplicate events must be considered, and failures need clear recovery strategies.
A small application that only checks occasional engagement totals may not need this architecture. A simpler scheduled process could be easier to maintain.
The value appears when scale and multiple downstream uses justify the additional infrastructure. In that situation, treating a like as an event can separate ingestion from processing, absorb bursts in activity, and allow new consumers to be introduced without tightly coupling every part of the system.
The important decision is not whether event-driven architecture sounds more advanced. It is whether the application’s volume, reliability requirements, and processing needs make that added flexibility worth the complexity.